preferred on


Points of Focus
- SIMD-0286 raised Solana’s maximum block compute from 60M to 100M CUs on July 29, while the per-writable-account limit remained at 12M CUs.
- The added capacity is most accessible to DEXs that distribute transactions across independent pools, markets, and writable-account sets.
- The thesis fails if an unchanged hot pool or market achieves a proportional throughput gain with stable CU use per transaction and the same writable-account structure.
Solana activated Solana Improvement Documents (SIMD) 0286 on July 29, 2026, raising maximum block compute from 60 million to 100 million compute units. The change raised the aggregate block compute budget by 66.7%, while the maximum compute assigned to any single writable account remained fixed at 12 million CUs per block.
This asymmetry changes where scaling pressure appears. Applications with transactions distributed across independent states can use more of the expanded block budget. Activity concentrated around one shared pool, market, vault, or order book continues to face the same local ceiling. The practical gain, therefore, depends on how an application partitions its writable state and how densely its transactions contend for the same accounts.
The previous limit constrained peak blocks
Solana’s block demand was uneven before the upgrade. The Solana Foundation reported in July 2026 that 11.2% of blocks produced from July 22, 2025, through the activation of SIMD-0286 consumed at least 56M CUs. The threshold sat 4M CUs below the former 60M limit. Approximately one block in nine operated close to the ceiling, with usage concentrated during periods of market volatility.
That distribution defines the problem SIMD-0286 addresses. The old ceiling restricted peak blocks carrying many simultaneous workloads. The increase creates another 40M CUs of execution space during those periods.
SIMD-0286 preserved the remaining resource limits:
| Protocol limit | Before July 29, 2026 | After July 29, 2026 |
| Maximum block compute | 60M CUs | 100M CUs |
| Maximum writable account compute | 12M CUs | 12M CUs |
| Maximum vote compute | 36M CUs | 36M CUs |
| Account data size delta | 100MB | 100MB |
Lucas Bruder of Jito Labs submitted the proposal on May 20, 2025. Its design explicitly links the flat writable-account limit to additional parallel capacity. The proposal also lists longer execution times, slower validator catch-up, and pressure on external infrastructure among the risks of larger blocks.
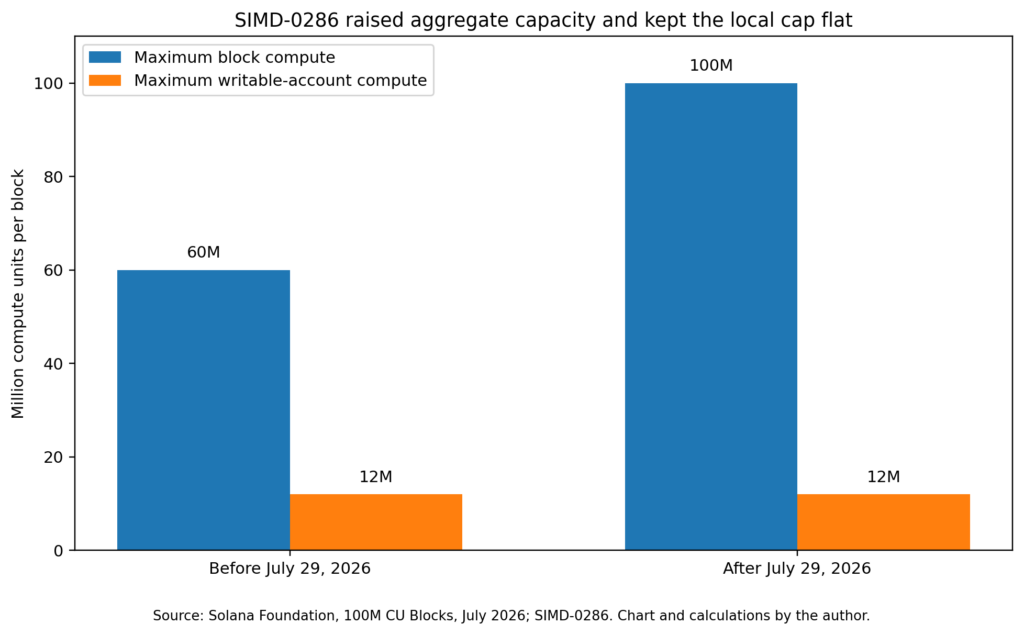
Solana enforces two separate compute ceilings
A transaction consumes part of the block-wide budget and part of the budget assigned to each writable account it touches. Solana’s transaction pipeline also locks writable accounts during execution. A transaction can encounter account contention even when the block retains unused compute. The runtime lists “AccountInUse” as a scheduling error when another transaction in the same batch already holds the relevant lock.
The 100M limit, therefore, creates capacity across independent states. Transactions writing to separate accounts can occupy additional block space. Transactions converging on the same mutable account remain grouped under the 12M ceiling.
State topology determines usable parallelism
The execution constraint can be represented as a conflict graph. Each pending transaction forms a node, while an edge connects transactions that require incompatible account locks. Transactions without conflicting writable accounts can be scheduled in parallel. Dense clusters around shared mutable state remain subject to serial execution pressure and the same local compute ceiling.
SIMD-0286 enlarges the total compute budget available to this graph. It leaves the underlying conflicts unchanged. A workload composed of many independent writable-account sets can spread into the additional 40M CUs. A workload organized around one highly connected account remains bounded by contention and the 12M-CU allowance.
State topology, therefore, determines how much of the expanded block budget an application can use. Pool design, vault structure, order-book partitioning, and shared auxiliary accounts shape the effective degree of parallelism. Two decentralized exchanges (DEXs) with similar transaction costs may capture different gains from the same capacity increase because their writable-state dependencies are organized differently.
The distinction becomes clearer inside actual DEX execution paths.
Orca gains capacity across pools
An Orca Whirlpool swap writes to the Whirlpool account, the two pool vaults, the trader’s token accounts, and as many as three tick-array accounts. Pools using adaptive fees can also write to an oracle account. The shared pool state appears directly in Orca’s Swap account structure.
Swaps routed through different Whirlpools use different pool accounts, vaults, and tick arrays. Solana can schedule those workloads across the enlarged block budget. Heavy trading inside one Whirlpool repeatedly targets the same pool account and vault set.
The upgrade can accommodate more busy pools inside one block, leaving the compute available to the busiest individual pool unchanged.
OpenBook gains capacity across markets
OpenBook V2 follows a different trading model and reaches the same architectural boundary. Its order-placement code loads a trader-specific open-orders account and several shared market accounts: the market, bids, asks, event heap, and market vault.
Orders submitted to separate OpenBook markets use separate order books and market states. Those markets can consume more aggregate compute after SIMD-0286. Orders submitted to the same market continue writing to its shared bids, asks, market, and event-heap accounts.
The two designs use different execution logic, yet both partition capacity at the pool or market level.
| DEX operation | Core shared writable state | Natural unit of parallel capacity |
| Orca Whirlpool swap | Whirlpool, pool vaults, tick arrays | Separate pool |
| OpenBook V2 order placement | Market, bids, asks, event heap, market vault | Separate market |
This comparison adds a practical meaning to the protocol’s “parallel capacity” claim. The upgrade increases the number of independent markets that can be active in the same block. It provides no automatic multiplier for transactions concentrated inside one market.

Five hotspots no longer fill the block
The unchanged 12M writable-account limit allows a simple upper-bound calculation.
A saturated writable account represented as much as 20% of a 60M block. The same 12M allowance represents 12% of a 100M block.
Five disjoint workloads consuming 12M CUs each would exhaust the previous block budget:
5 × 12M = 60M CUs
Under the new limit, the same workloads leave 40M CUs available:
100M − 60M = 40M CUs
The 100M budget can accommodate up to eight disjoint 12M-CU workloads, plus another 4M CUs. That raises the theoretical number of fully saturated independent workloads from five to eight, or 60%.
This calculation assumes that the workloads use separate writable-account sets and encounter no binding transaction, vote, or account-data limit. It describes the capacity made available by the protocol limits, rather than guaranteed application throughput.
A DEX with activity distributed across independent pools or markets can draw on that expansion. Activity converging on one shared pool or market account remains inside the same 12M allowance.
Larger blocks still help a hot market
The strongest counterargument concerns spillover congestion.
A popular pool can gain better inclusion conditions even when its local ceiling stays fixed. Under the previous configuration, unrelated applications could consume the remainder of a 60M block. Their activity increased competition for the aggregate block budget. SIMD-0286 gives validators another 40M CUs for those independent transactions.
This indirect benefit can reduce competition surrounding a hotspot. It can also create more room for transactions that interact with the same application through different accounts.
The account ceiling still determines the direct throughput available to the shared pool or market state. A proportional throughput increase requires lower CU use per transaction, additional state partitions, or a redesigned execution path.
The empirical test belongs at the account level
Block utilization alone cannot show which applications captured the additional capacity. A post-activation analysis should compare periods with similar market volume and volatility across five measurements:
- CUs charged to the busiest writable accounts
- Successful swaps or orders per slot within the same pool or market
- Priority fees paid per successful transaction
- Total block utilization during the same slots
- Throughput across separate pools or markets within the same protocol.
The thesis is supported if throughput rises across independent markets as block utilization moves beyond 60M CUs, while activity within a single market continues to flatten near the writable-account ceiling. It is weakened if an unchanged hot account produces a throughput increase close to 66.7% with stable CU use per transaction.
As of Aug. 5, the available official material documents the new limits and the historical block-capacity constraint but does not include the account-level post-activation data needed to run this test.
Application architecture now shapes access to added blockspace
SIMD-0286 removes a documented constraint from Solana’s busiest blocks. Subject to the remaining protocol limits, the expanded budget can fit up to three additional disjoint 12M-CU workloads. Five fully saturated, non-overlapping workloads now consume 60M CUs and leave another 40M CUs available to unrelated activity.
The Orca and OpenBook execution paths show how applications can capture that capacity. Independent pools and markets can run alongside one another because they write to separate account sets. Activity concentrated within one pool or market continues to converge on the same shared state.
With the block ceiling raised from 60M to 100M CUs, state design becomes a more visible determinant of application-level throughput. DEXs that partition pools, vaults, order books, and market state can make fuller use of the additional blockspace. Applications organized around a small set of shared writable accounts gain better inclusion conditions while retaining the same local compute ceiling.
Disclosure: The author holds no financial position in SOL and has no financial relationship with Solana Foundation, Jito Labs, Orca, OpenBook, or Anza.