preferred on

Points of Focus
- Its biggest measured gains appear in systems that search old transactions and process large numbers of Bitcoin queries.
- Default nodes also get smaller improvements to validation and transaction relay.
- Production data after release will show whether the storage and CPU savings hold up under real workloads.
Bitcoin adds a new block roughly every 10 minutes. Every block becomes another piece of history that somebody may eventually need to store, verify, or search.
Bitcoin Core 32, the next major version of Bitcoin’s reference software, contains a series of changes aimed at making that history cheaper to work with.
The clearest example is an optional database called “txindex.” It acts like a lookup table for old transactions. With the index enabled, software can ask Bitcoin Core for a transaction from years ago without first knowing which block contains it.
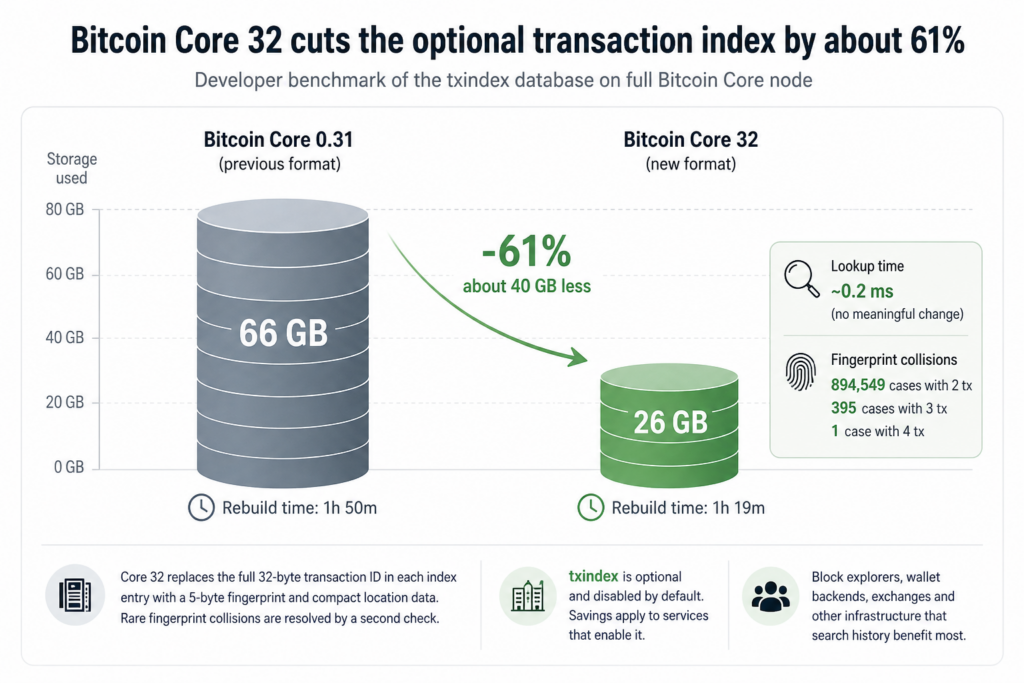
In a developer benchmark published with PR #35531, the new version of that index occupied about 26 GB, down from about 66 GB. Rebuilding it took 1 hour 19 minutes, compared with 1 hour 50 minutes using the previous format. Transaction lookup time remained around 0.2 milliseconds.
Bitcoin Core disables the index by default, so the 40 GB saved is concentrated in infrastructure that keeps it enabled. Block explorers, wallet backends, exchanges, and other services that search Bitcoin’s history are the most obvious beneficiaries.
Bitcoin Core 32 entered feature freeze on Aug. 20. As of Aug. 26, its first release candidate is scheduled for Sept. 10, with the v32.0 tag targeted for Oct. 10. The benchmarks point to a specific pattern: Core 32’s largest efficiency gains accrue to nodes that run extra indexes or process unusually heavy queries. Ordinary validating nodes see smaller gains.
Bitcoin’s transaction lookup table shrinks by about 40 GB
The old transaction index stored the full 32-byte transaction ID in each database key.
On June 14, Bitcoin Core developer Pieter Wuille estimated that the index covered 1.376 billion transaction IDs. Repeating a 32-byte identifier more than 1 billion times adds a substantial storage cost.
Core 32 replaces that identifier inside the index with a much shorter fingerprint. The new format stores five bytes derived from the transaction ID, along with a compact description of where the transaction can be found. Core can then use information it already holds in memory to locate the relevant block.
Short fingerprints sometimes match more than one transaction. The final mainnet benchmark recorded 894,549 cases where two transactions shared the same fingerprint, 395 cases involving three transactions, and one involving four.
When that happens, Core reads the possible matches and checks the full transaction ID before returning an answer. Lookup time in the benchmark stayed around 0.2 milliseconds. Core stores less information for every transaction and performs an extra check when fingerprints collide. Repeated across more than 1 billion records, that change removes about 40 GB.
Operators can keep using an existing “txindex” after upgrading. They need to rebuild it to recover the full storage saving. Services with slower storage and heavy historical query traffic will provide the first real test of whether those collision checks remain cheap at scale.
Core 32 also cuts validation and indexing costs
The transaction index produces the biggest disk saving. Other changes reduce processing time elsewhere.
| Core 32 changes | Benchmark date | Previous result | New result |
| Transaction index size | Aug. 15 | about 66 GB | about 26 GB |
| Transaction index rebuild | Aug. 15 | 1h50m | 1h19m |
| Spent output index size | July 11 | 85.0 GiB | 80.9 GiB |
| Spent output index sync | July 11 | 4h37m | 3h57m |
| Chain state reindex | July 21 | 11,278 seconds | 10,759 seconds |
| Large spending query, desktop | Aug. 4 | 90 seconds | 10 seconds |
| Large spending query, Raspberry Pi 5 | Aug. 4 | 685 seconds | 22 seconds |
One improvement reaches a basic job performed by every validating Bitcoin node. Bitcoin Core keeps a record of Bitcoin outputs that have been created and have not yet been spent. Developers call this the unspent transaction output (UTXO) set. Every new transaction has to be checked against it.
PR #35215 makes those lookups cheaper. In a benchmark included when the change merged on July 21, rebuilding Bitcoin’s chain state through block 957,759 took an average of 10,759 seconds, down from 11,278 seconds on the same Ryzen 7 3700X system with an SSD. That is a reduction of 519 seconds, or about 4.6%.
Another change cleans up an optional database used to find which transaction eventually spent a particular Bitcoin output. The database had been maintaining an extra structure designed to speed up a type of search it never used. Removing it cut a July 11 benchmarked sync from 4 hours 37 minutes to 3 hours 57 minutes. The database shrank from 85.0 GiB to 80.9 GiB. The software was spending time and disk space maintaining data that its normal searches never consulted.
One spending query was moving data tens of millions of times
The largest speedup in Core 32 comes from a problem buried inside a single query. Bitcoin Core allows outside software to send it a list of outputs and ask which ones have already been spent. Wallet backends and other services can use this when following chains of transactions.
The old code handled very large batches inefficiently. Each time Core found an answer, it removed that request from the middle of a list. Everything behind it had to shift position.
A developer model published Aug. 4 estimated close to 50 million moves for 10,000 matching requests. PR #35889 changes the way results are stored so the software can move through the request once. The benchmark used unusually large batches from 8,000 to 128,000 entries, with 10 repetitions at each size.
On a Ryzen 7 3700X desktop, total execution time fell from 90 seconds to 10 seconds. On a Raspberry Pi 5, it fell from 685 seconds to 22 seconds. The 31.1x figure applies to this stress test and should not be read as an overall performance gain for Bitcoin Core.
The hardware comparison still reveals the cost of the old algorithm. The same oversized request took 90 seconds on a desktop and more than 11 minutes on a Raspberry Pi 5. Core 32 cuts the Raspberry Pi result to 22 seconds.
The 40 GB saved is concentrated in indexed nodes
The biggest Core 32 numbers need context. Bitcoin Core keeps “txindex” disabled by default, and its spent output index is optional, too. A standard node, therefore, has no 66 GB transaction index to shrink and no 85 GiB spender database to reduce. The large spending query benchmark also uses workloads far beyond what many nodes will ever see.
For a typical validating node, the 4.6% chain state reindex improvement gives a better indication of the release’s direct performance gains. The headline savings are concentrated in nodes running additional indexes and heavy historical queries, while default-node improvements measured so far are smaller.
Bitcoin services pay to make old transactions searchable
Running a Bitcoin service requires more than storing blocks. Historical transactions also have to be indexed, retrieved, and connected to later spends.
A block explorer has to find old transactions quickly. An exchange backend may query thousands of transactions and outputs. Wallet services inspect the mempool and historical chain data. Lightning software may need to discover which transaction spent an older output.
Those jobs create extra databases and query paths around the blockchain.
A draft Eclair proposal opened in April 2026 gives one concrete example. ACINQ developers want the Lightning implementation to use Bitcoin Core’s spent output index because scanning old blocks is expensive and can only reach so far into the past. On Aug. 21, they said they planned to wait for Bitcoin Core 32 before merging the change, citing the smaller storage footprint of the redesigned index.
Core 32 makes this kind of infrastructure cheaper to operate by shrinking indexes and removing work from queries that services may run thousands of times.
Shared relay queues cut repeated peer bookkeeping
Core 32 also changes how nodes manage transactions waiting to be sent to peers.
Bitcoin nodes constantly tell one another about new transactions. The previous relay system applied rate limiting through queues maintained separately for each peer, so CPU and memory use could grow with both the queue and the number of connected peers.
PR #34628, merged July 25, replaces that rate-limiting mechanism with a global queue. Per-peer queues remain for privacy-related batching, but they no longer carry the same rate-limiting workload. Developers estimate that this reduces the relevant memory and CPU scaling during transaction spikes from the size of the queue multiplied by the number of peers to the size of the queue alone.
The bigger test comes after Core 32 ships
Most of the numbers available today come from developer machines, and production operators will provide a tougher test.
If rebuilt transaction indexes recover much less than the roughly 40 GB seen in the developer benchmark, the storage case weakens. If shorter transaction fingerprints noticeably slow historical searches under sustained traffic, the disk saving comes with a higher query cost. If standard nodes eventually show gains similar to indexed services, Core 32’s benefits will prove more evenly distributed than the current benchmarks suggest.
For now, the strongest measured gains sit in the machinery used to organize and search Bitcoin’s expanding history. A transaction lookup table falls from about 66 GB to 26 GB, an unused database structure disappears, and a large query stops moving the same data tens of millions of times.
Bitcoin will keep accumulating history, and Core 32 shows how much room remains to make that history cheaper to work with.